SciLM Subsurface
Give it the field's data. Get every geology that fits.
Wells, seismic and the field's production history go in. Every geology consistent with all three comes back, as an ensemble, in hours, and a surrogate forecasts production for any development plan on every one of them in seconds. History matching is the biggest problem in reservoir simulation; the decision behind it, the field development plan, is where the money is. One tool does both.
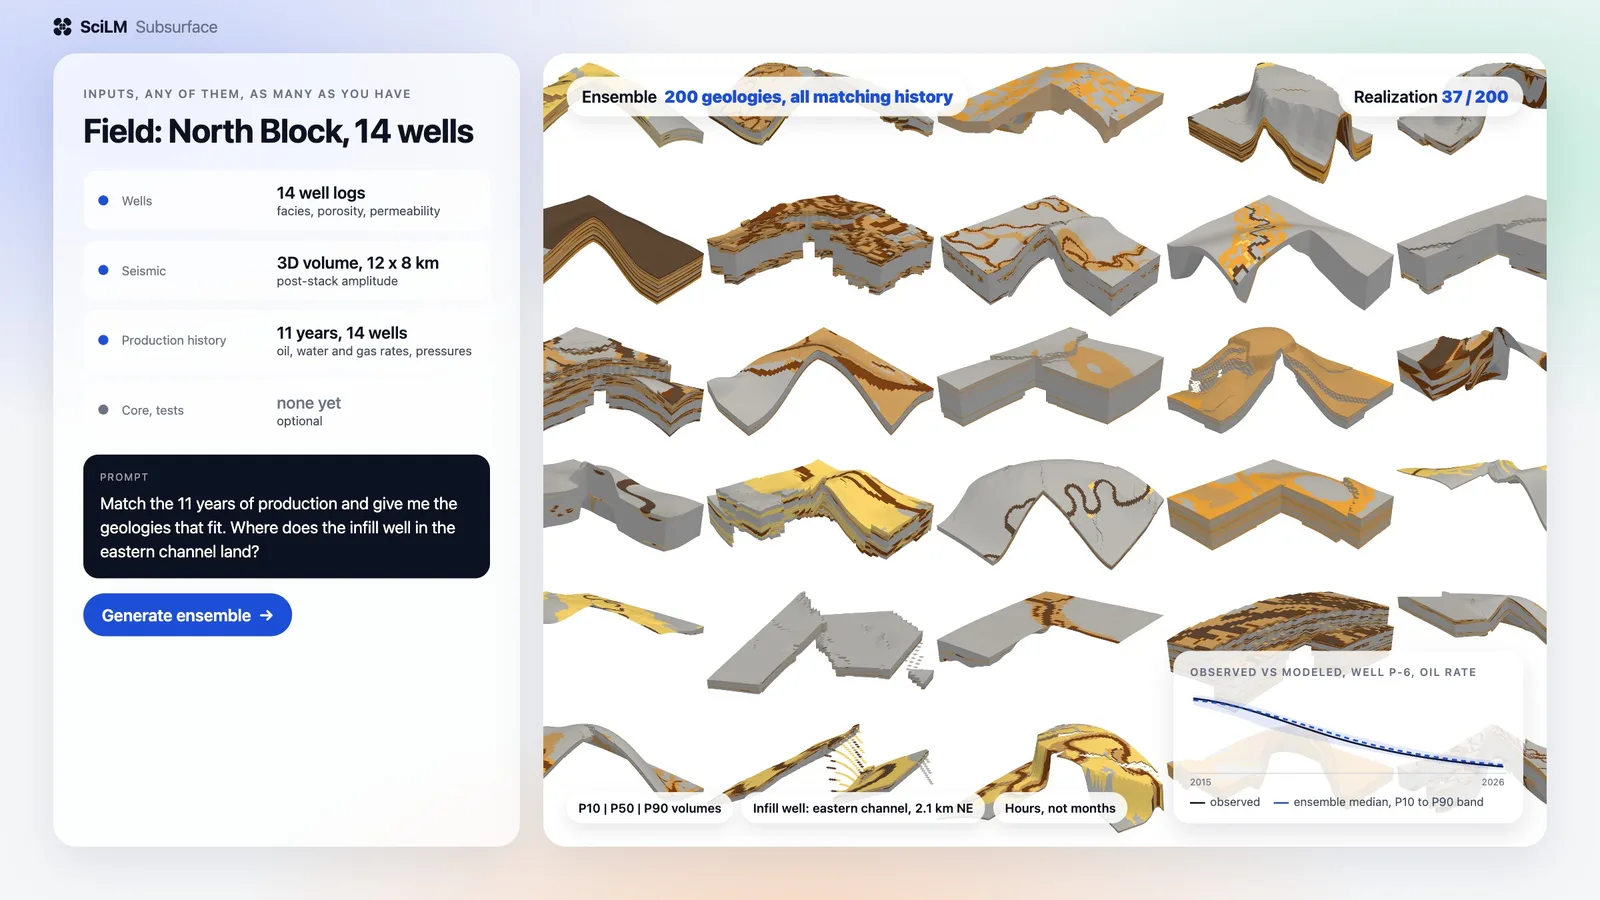
The interface as designed; the model behind it is described below.
What you give it
- Wells: logs, facies, porosity and permeability, any number and orientation.
- Seismic: a post-stack volume, when you have one.
- Production history: oil, water and gas rates and pressures per well, over the life of the field.
- Anything else: core, tests, a prompt for what you expect. Nothing is required.
What you get
- An ensemble of geologies that honor every well and match the production history, in hours, not months.
- Facies, porosity and permeability in every voxel, in the format your simulator reads.
- A pre-trained surrogate: production for any geology and any development plan in seconds, in place of a simulation run that takes hours or days, with no retraining per geology.
- Field plans, wells and schedules optimized under uncertainty: every plan tested on every geology that fits, with P10, P50 and P90 instead of one hand-tuned model.
How it works.
It learned geology from a million reservoirs. We generated SiliciclasticReservoirs, one million 3D reservoirs across eight depositional architectures, with the rules geologists use, and trained ResFlow on them: one flow-matching model that generates any of those architectures, conditions on any number, location and orientation of wells, and assembles fields of any size.
One dataset, both directions. We simulated flow through the reservoirs we generated, so the same data trains two models that are nearly one model inverted: given a geology and a plan, predict the production, which is the surrogate; given the production, recover the geologies, which is the inverse. The surrogate turns a simulation run of hours or days into a forecast in seconds, and because it is pre-trained it needs no retraining for each new geology, which is what makes trying hundreds of geologies and well schedules for one field development plan possible at all. A surrogate trained per geology would defeat the purpose.
It reads production history as data, not as text. An LLM can write a script, but it cannot create or edit a geology from a prompt or from a new kind of data. SciLM Subsurface is the only generative model that learns geology directly from observed production history, alongside the wells and the seismic, so the ensemble it returns is the one the field's own behavior selects.
It gives an expert's first guess. A text model starts each round of history matching from whatever a simulator hands it. A model trained on the geology itself starts close to the answer, the way an experienced reservoir engineer does, and reaches it with fewer expensive simulation runs.